
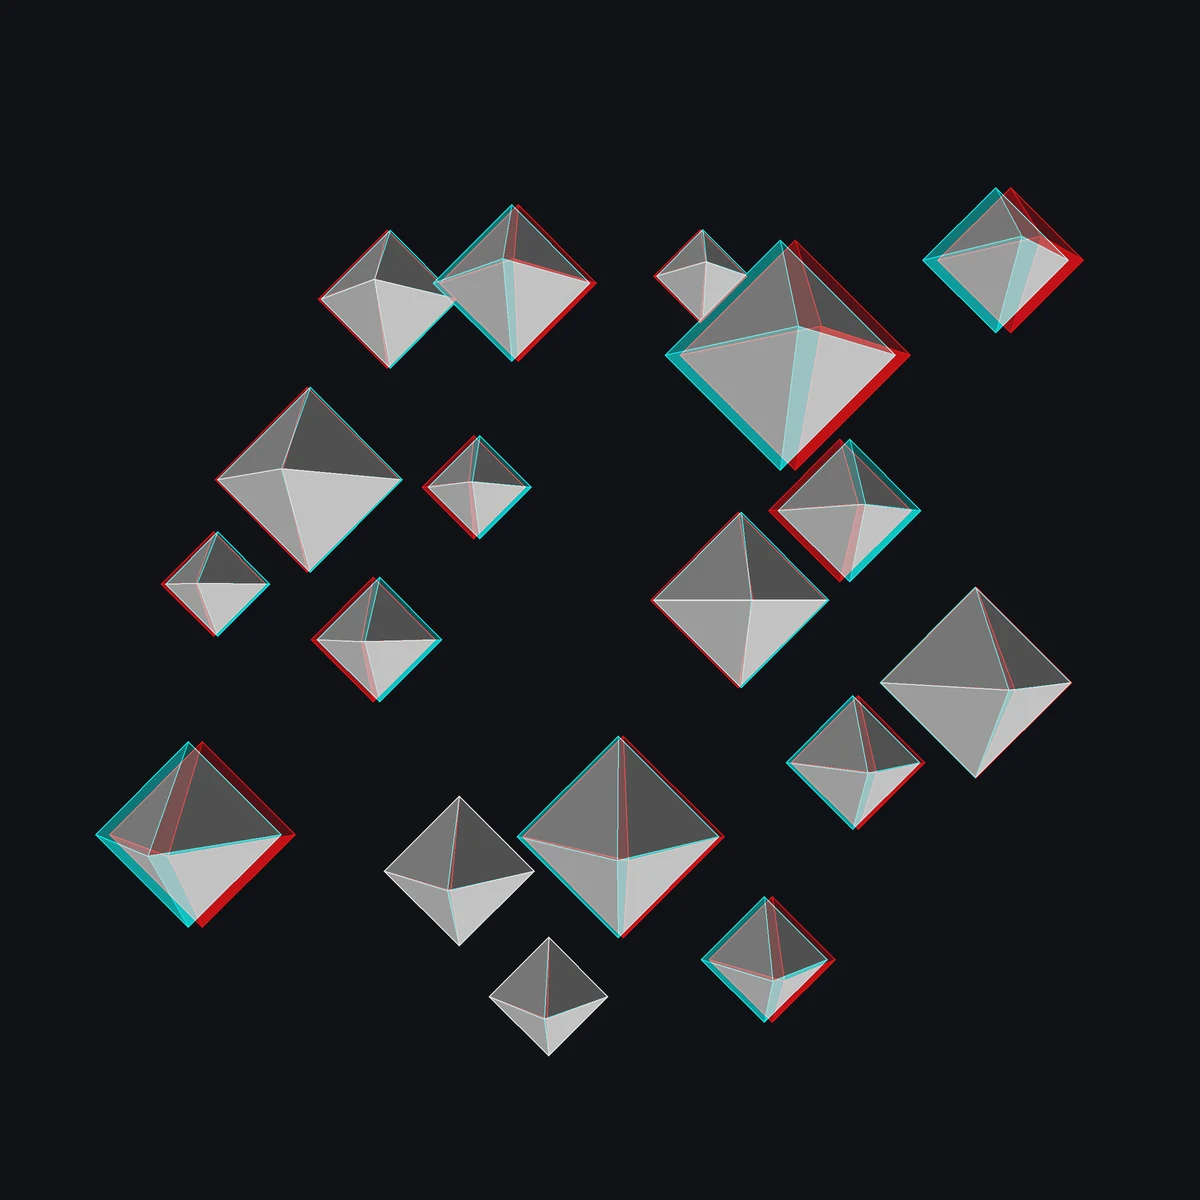
A seeded scene places faceted solids at explicit three-dimensional coordinates. Converged left and right perspective cameras render the same surfaces; the final image takes red from the left view and green/blue from the right, with both original views retained. Scene construction and both camera renders are local, with no generation calls. More objects and larger canvases increase local drawing work; suitable viewing glasses are separate from the digital output.
- Needs
- Python 3
v1.0.0 · Updated Oct 25, 2026 · 401 KB · Use it for personal and client work; please don't resell or share the package.
What you get
Red-cyan anaglyph PNG and raster-wrapped SVG
Separate left/right PNG and editable vector views
Scene ledger, local view switcher and portable brief
Good for
- Geometric stereoscopic art and depth studies
- Comparing a stereo pair with its combined view
Not for
- Estimating real depth from a photograph
- Glasses-free depth or guaranteed perception on every display
How it works
Includes a local renderer
Choose the input
Set a geometric scene seed, depth spread and eye separation.
Render and inspect
Render both perspective views and combine their color channels.
Adjust and export
Switch between the component views and inspect the anaglyph with suitable glasses.
How the workflow runs
How Stereo anaglyph shadowbox works
A seeded scene places faceted solids at explicit three-dimensional coordinates. Converged left and right perspective cameras render the same surfaces; the final image takes red from the left view and green/blue from the right, with both original views retained.
What's inside the skill
What you can change
- eye_separation: 0.02–0.22 scene units
- layer_depth: 0.3–1.8
- object_count: 8–30 and focal_length: 2.5–6
- Scene seed and output dimensions
What to review before delivery
- Left and right rendered views differ in actual pixels.
- The scene ledger contains the requested object count.
- The saved brief reproduces the PNG and SVG; unsafe replacement is rejected.
See the package files
These are selected working files from this edition, with their actual role. The complete download also contains instructions and applicable license notices.
The domain algorithm and invariant checks.
scripts/recipe.pyRunnable, editable example parameters.
examples/brief.jsonControl meanings, proof interpretation and limits.
references/design-notes.md
Why use this skill
Start with this package
The workflow supplies an explicit scene, camera pair and inspectable component exports. It avoids faking binocular depth with a single flat-image offset or an unexplained color filter.
Compare the options
A prompt, your own skill, or this workflow?
Start with a prompt
Your agent can create from a plain request. The brief, visual rules, asset choices, output format and review process still need to be established for that project.
Write your own skill
You choose and maintain the reusable instructions, defaults, file structure and checks. This is useful when your process needs different rules or integrations.
A workflow created for PopNow
This workflow was built for PopNow. Its source files, included dependencies and applicable notices are part of the package; the scope described below belongs to this edition.
Guide reviewed Oct 25, 2026
What will this cost?
Scene construction and both camera renders are local, with no generation calls. More objects and larger canvases increase local drawing work; suitable viewing glasses are separate from the digital output.
The supplied route runs locally. A new-media request is a separate choice. Free skill. New media is quoted before it runs.
The skill package
Free to install under your account's download allowance. The package license covers your own and client work; redistribution is excluded.
Existing assets and local work
Reusing suitable assets, editing files and running local assembly do not call a PopNow generation model. Your computer and any required runtime still do the work.
Your agent and hosting
Any subscription, hosted computer, deployment or other provider fee belongs to that service. Installing this skill does not include those services.
How PopNow billing works
Connections using a PopNow API key, including API-key MCP connections, spend from the separate API balance in USD. A ChatGPT or Claude connection authorized through OAuth spends website credits. These balances are separate; the quote shown by your connection is the approval basis.
Download allowances and current account conditions apply. A free package does not mean unlimited free generation.
How to use it
You say
Use the PopNow skill "Stereo anaglyph shadowbox" (stereo-anaglyph-shadowbox) for this: Set a geometric scene seed, depth spread and eye separation. Use the packaged example as a starting point and return the actual artwork with its editable inputs.
Then try
Rebuild a visibly different version using eye_separation: 0.10 → 0.18; layer_depth: 1.2 → 1.6.
Explain the result using its actual proof files and algorithm ledger.
What to have ready
- Desired object count and depth spread
- Red-left/cyan-right glasses to inspect stereo depth
- Python 3.10+, Pillow and NumPy
Similar skills
View all → Image
Geometric shape portrait
+25Rebuild a portrait from translucent triangle layers that remain individually editable in SVG.
 Image
Aperiodic mosaic art
+25Create a colored rhombus mosaic from a five-direction grid, with no repeating wallpaper tile.
 Image
Stained Glass Suncatcher Design
+25Build a textured botanical glass artwork from closed flower, leaf and irregular background panes.
 Image
Double Exposure Silhouette
+25Blend a separate landscape through an explicit silhouette mask, keeping both layers and the mask editable.
 Image
Embroidered Travel Patch
+25Create a tactile patch concept with a limited thread palette, a cut contour and a practical design handoff.
 Image
Collectible Figure Mockup
+25You, your pet or your own character as a desk figure, a boxed toy, a cut-out and a turntable clip.
 Image
Packaging Mockup Generator
+25Your flat packaging art on boxes, pouches and jars, in shelf and unboxing scenes, checked word for word.
 Image
Embossed letterpress poster
+25Shape real font glyphs into a shaded paper relief, with editable type outlines and lighting.
 Image
Guilloche rosette maker
+25Draw fine ornamental rosettes from exact gear ratios and export the closed vector paths.
 Image
Stippled ink portrait
+25Turn photographic tone into thousands of individually editable ink dots and a close-up proof.
 Image
Contour terrain poster
+25Extract real contour paths from a synthetic terrain or your own grayscale heightmap.
 Image
Wireframe sculpture print
+25Render a twisted three-dimensional sculpture as editable lines with real hidden-surface removal.
 Image
Image quilting studio
+25Grow a texture swatch into a larger artwork using matched patches and actual minimum-cost seams.
 Image
Procedural ink landscape
+25Build a panoramic ink landscape from seeded ridges, textured strokes, trees and open water.
 Image
Invented specimen etching
+25Draw an imaginary fish with organic fin contours, individual scales and layered engraving strokes.
 Image
Hybrid distance illusion
+25Blend two aligned images by frequency so the visible subject changes with viewing scale.
 Image
Calligram silhouette poster
+25Build a silhouette from real words, with collision-aware placement and editable SVG text.
 Image
AI Logo Generator
+25Pick from 3-5 symbol directions, get an SVG logo kit with lockups, one-colour versions and favicons.
 Image
AI Tattoo Design Studio
+25Create your own tattoo design in three styles, then a real-size stencil and a try-on on your own photo.
 Image
AI Wallpaper Generator
+25One original wallpaper, extended and upscaled for every screen: phones, 4K-5K, ultrawide and dual monitors.
 Image
Album Cover Art Kit
+25Song title and mood in, a 3000x3000 cover with exact type, a seamless loop and promo images out.
 Image
Amazon A+ Content Builder
+25Product photos and facts in; exact-size A+ module images, claim-checked copy and a phone preview out.
 Image
App and UI Icon Generator
+25One app icon and 10-30 matching UI icons, exported for iOS, Android adaptive, PWA and favicons.
 Image
Apparel On-Model Lookbook
+25Flat-lay clothing photos in, a lookbook on one AI-generated model out, with poses, angles and walk clips.
 Image
Barrier Grid Animation Card
+25Interlace painted hummingbird poses and reveal them through an actual sliding barrier grid.
 Image
Biological Pathway Diagram
+25Create editable pathway maps with checked node links, explicit interaction types and evidence notes.
 Image
Black and White Studio Portrait
+25Turn an everyday photo into a calm black-and-white studio portrait that still looks like you.
 Image
Blog Post Illustration Set
+25Three matching illustrations for one article, each showing what its passage actually says.
 Image
Book Cover Designer
+25Title, author and genre in: three cover directions, an exact-type ebook cover and a print-ready wrap.
 Image
Brand Kit & DESIGN.md Generator
+25A brand kit from a short brief: checked palette, open fonts, SVG logo, mockups and a DESIGN.md agents follow.
 Image
Calm Illustrated OG Image Maker
+25Friendly link previews: ivory field, floating phones, soft doodles and a rounded headline, at 1200x630.
 Image
Car Cutaway Anatomy Poster
+25A side-view cutaway of a generic car: color-coded systems, numbered markers and round zoom windows.
 Image
Carousel Post Maker
+25Article or opinion in, a 6-10 page carousel out: LinkedIn PDF, Instagram 4:5 and RedNote 3:4.
 Image
Catering Menu Designer
+25A menu spreadsheet in: a print menu, tri-fold, table tent and a phone menu for a QR code, prices checked.
 Image
Chalkboard Infographic Maker
+25A 16:9 chalkboard-style infographic with exact short copy, chalk drawings and one clear reading path.
 Image
Cinematic Storyboard Frames
+25Three storyboard contact sheets for one scene, each a different way to shoot it, with continuity kept.
 Image
Coloring Book Generator
+25A theme in, a print-ready coloring book out: clean line art, 300 DPI pages and a paperback interior PDF.
 Image
Concept Metaphor Illustration
+25One idea, one hand-drawn visual metaphor: flat muted color, off-white cut shapes, loose black marker lines.
 Image
Consistent Concept Art Set
+25A character, a prop and an environment that clearly belong to the same fictional world.
 Image
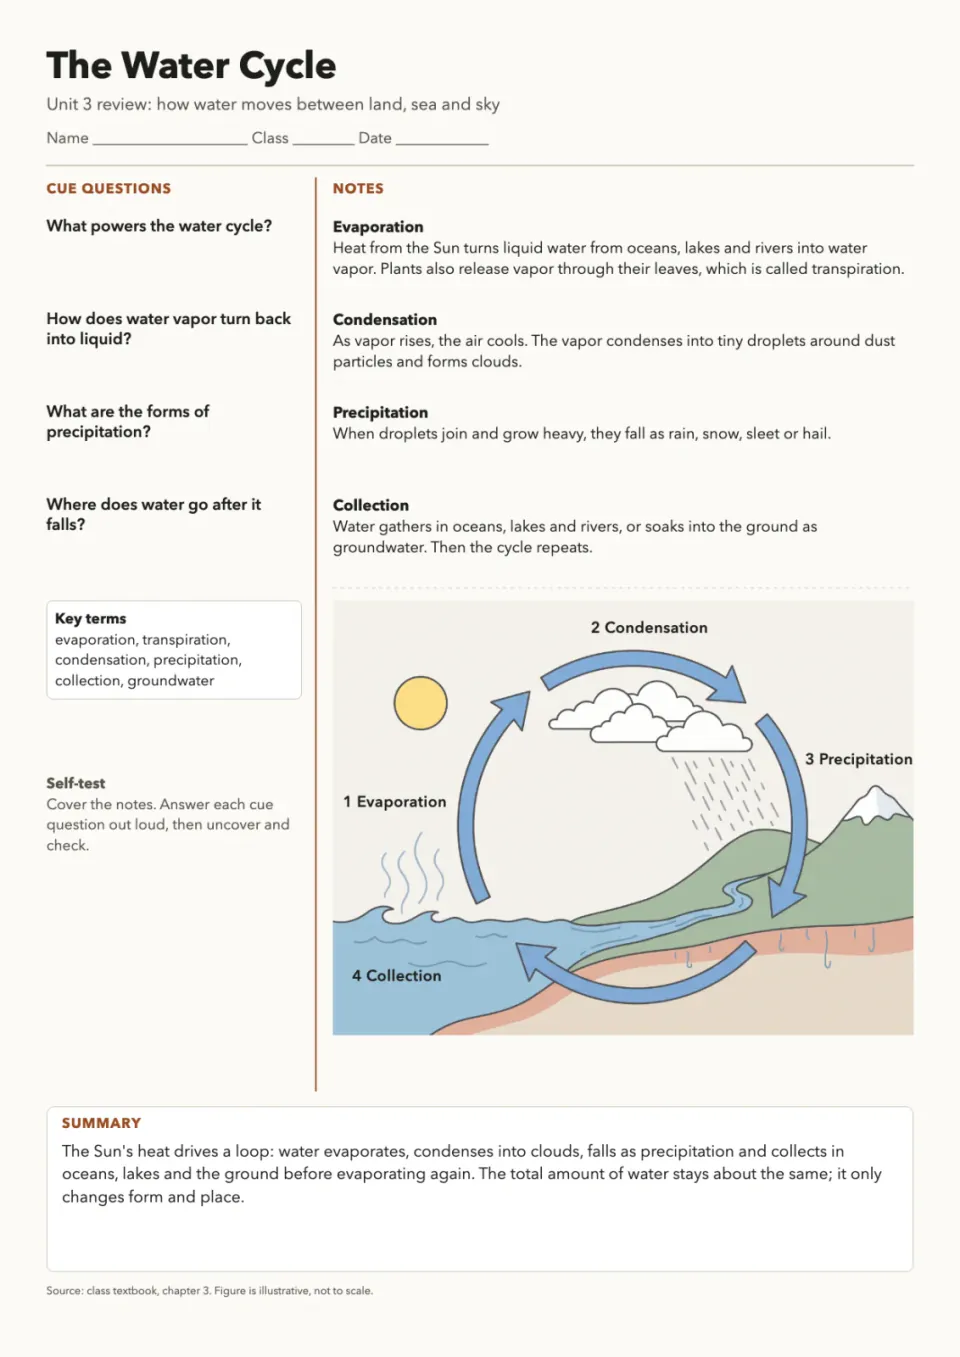
Cornell Notes Study Sheet
+25A printable two-column revision page with cue questions, notes, a drawn figure and a fill-in practice copy.
 Image
Cute Crayon Doodle Art
+25Lovably clumsy crayon characters on white paper: wobbly lines, scribbled fills, sharp files, sticker cut-outs.
 Image
Cute Mascot Avatar Maker
+25Round, two-eyed mascot avatars or chibi vinyl-toy characters, with a cut-out and a profile-size set.
 Image
Cyanotype Botanical Print
+25Compose a blue-and-white botanical contact-print artwork with paper borders and measured tonal separation.
 Image
Die-Cut Sticker Sheet Maker
+258 to 24 matching stickers, cut out with white borders, on print-ready A4 or Letter sheets plus chat packs.
 Image
Ecommerce Product Photo Studio
+25A folder of product snapshots in, white main images, scene shots and banners out, checked for Amazon and Etsy.
 Image
Editorial Line Illustration
+25Airy black-ink illustrations with one accent color for blog headers, newsletters and social cards.
 Image
Editorial Still Life Composition
+25Compose editable object studies with rotated-boundary checks, deliberate layering and a print-ready SVG.
 Image
Engraving Style Article Cover
+25One surreal black-ink engraving per essay: crosshatched, edge to edge, its big idea shown as a single scene.
 Image
EV Platform Exploded View
+25An electric car lifted apart layer by layer: battery, motors, cabin and body in color, with callouts.
 Image
Event Flyer Maker
+25Event details in: a flyer for A4, Letter or A5 print plus square, portrait and story images, with a QR code.
 Image
Product Exploded View Poster
+25A clean exploded-view hero image of a product, with exact part labels from your spec table.
 Image
Fantasy Map Generator
+25Parchment, atlas or black-line maps of your own world, every name lettered right, grids that line up.
 Image
Film Poster OG Image Maker
+25Quiet, poster-like link previews: black-and-white close-up, one huge black word, film grain, exact 1200x630.
 Image
Floor Plan to 3D
+25A 2D floor plan in, a furnished 3D floor plan out: bird's-eye, angle and evening views plus a showcase page.
 Image
Folded Paper Cityscape
+25Create a sculptural paper-city artwork with editable framing, named fold guides and a consistent light plan.
 Image
Regional Food Flavor Map
+25A calm painted map of regions, each with a small taste chart on one shared scale and an honest legend.
 Image
2D Game Asset Pack Maker
+25A matching 2D game art pack: posed character, tiles, props and icons, packed into sprite sheets with JSON.
 Image
Hidden Stereogram Poster
+25Hide a simple depth shape in a repeating random-dot image, with a plain depth reference always included.
 Image
Holiday Card & Invitation Maker
+25One greeting in: print-ready 5x7 cards, social and story versions, an animated e-card and an RSVP page.
 Image
Illustrated City Map Maker
+25A hand-drawn style map of a neighborhood or town, true where it matters and labeled exactly.
 Image
Industrial Specification Poster
+25Build editable technical posters with normalized dimensions, tolerances and traceable specification tables.
 Image
Ink Sketch Storyboard
+25A rough black-ink storyboard page from a short story: open lines, white space, one beat per panel.
 Image
Interlaced Knot Art
+25Draw a closed, lustrous woven knot with real over-and-under crossings and editable vector paths.
 Image
Kids Picture Book Maker
+25A story idea in, a printable picture book out, with one consistent hero, a web flip-book and a bedtime video.
 Image
Line Art OG Image Maker
+25Calm link-preview images: off-white card, short black headline and a hand-drawn ink character.
 Image
Manga Panel Maker
+25Original manga pages from your script: locked characters, real panel layouts and lettering in real fonts.
 Image
Marine Biology Research Poster
+25A wide research poster around a painted habitat cross-section, with numbered species and a findings chart.
 Image
Miniature Diorama & Weather Card
+25Tiny isometric cities, rooms and tilt-shift scenes, with exact-text weather cards, a loop and 4K wallpapers.
 Image
Negative Space Illusion
+25Two cranes frame one full moon through an exact shared boundary; swap figure and ground to read it again.
 Image
Old Photo Restoration
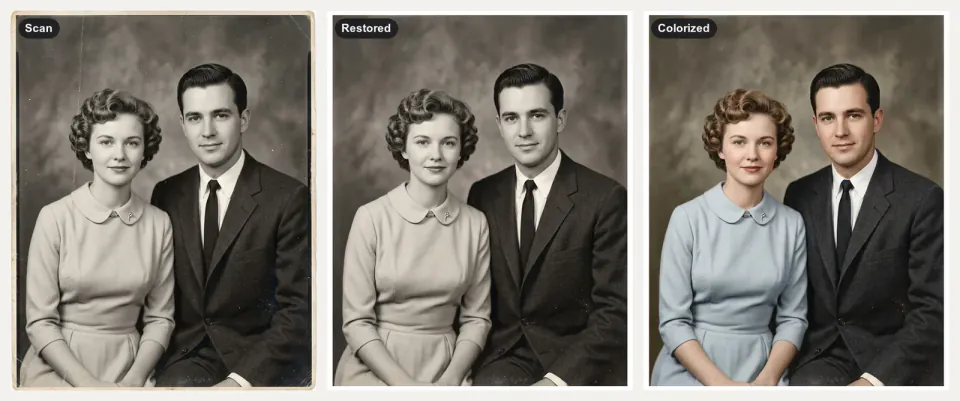
+25Scratched, faded family photos in, faithful restorations, color estimates and gentle living photos out.
 Image
Optical Experiment Diagram
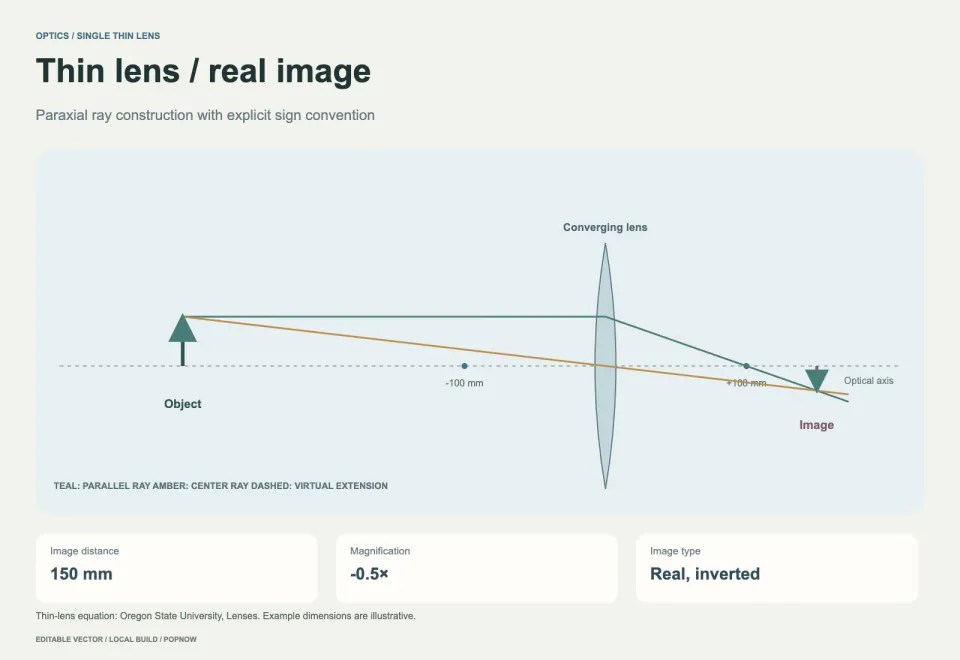
+25Draw editable thin-lens ray diagrams with calculated image distance, magnification and units.
 Image
Pet Portrait Studio
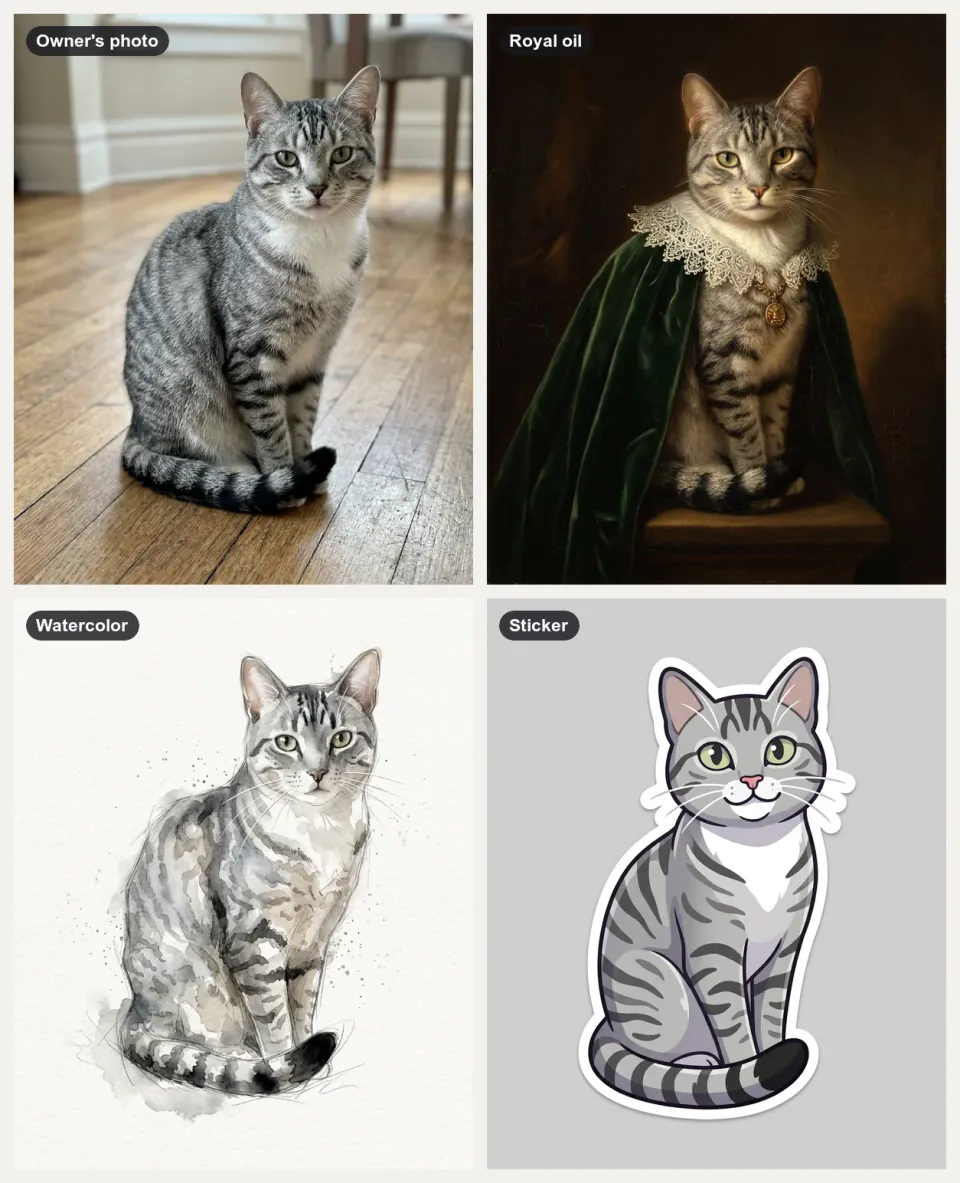
+25Your pet in the styles you pick, plus a sticker, a short clip and print files, with every marking kept.
 Image
Phone Mockup Generator
+25Your app on a 3D foldable phone that swings open on a soft backdrop, as crisp PNG stills or a fold clip.
 Image
Photo Composition Studies
+25Three photographic takes on one subject, each built on a different composition principle.
 Image
Photo Mosaic Memory Poster
+25Build a recognizable silhouette from photo tiles, with every crop and reuse count recorded.
 Image
Product Cross-Section Diagram
+25A cutaway of your product showing each layer in real order, with numbered callouts from your spec sheet.
 Image
Quote Card Maker
+25Square and 4:5 quote cards with exact text, a checked credit or handle, and a line drawing of the idea.
 Image
Real Estate Listing Photo Kit
+25Property photos in, cleaned and labeled listing images, staged rooms, tour clips and a listing PDF out.
 Image
Research Graphical Abstract
+25Turn a research brief into editable question–method–result artwork with source-linked measurements.
 Image
Seamless Surface Pattern
+25Arrange detailed botanical motifs into a true repeating tile, with a full 3 by 3 seam proof.
 Image
Sketchnote Image Generator
+25Turns an article or notes into one hand-drawn 4:3 sketchnote with exact, checked labels.
 Image
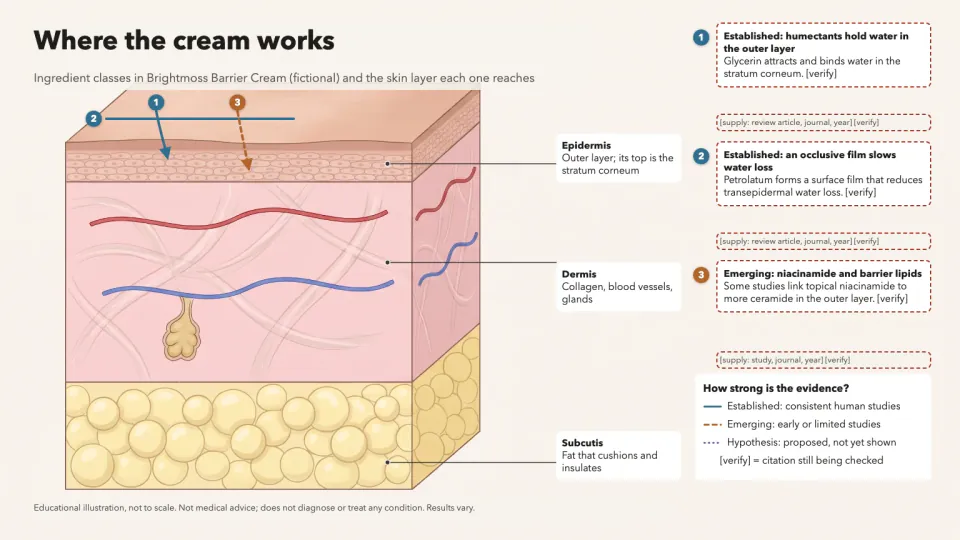
Skincare Science Diagram
+25A skin layer diagram showing where ingredients act, with evidence-styled arrows and a source on every claim.
 Image
Social Cover & Thumbnail Generator
+25One message in, a checked set of OG images, post covers and video thumbnails out, every size exact.
 Image
String Art Portrait
+25Rebuild a portrait as one continuous nail-to-nail thread path with editable pins and numbered line order.
 Image
Surreal Miniature Poster
+25Turn one impossible scale relationship into an editorial poster with editable type and real resolution checks.
 Image
Trading Card Maker
+25A spreadsheet of names and stats in: a matching set of original cards, print-ready at 63 x 88 mm.
 Image
T-Shirt Design Generator
+25Original shirt designs as print-ready transparent PNGs at 300 DPI, plus flat-lay and on-model mockups.
 Image
Two-Ink Risograph Print
+25Separate a photograph into fine two-ink halftones, with a composed headline and real ink plates.
 Image
Watercolor Concept Diagram
+25A watercolor illustration of how something works, with fine ink lines, clean label lanes and exact callouts.
 Image
Wedding Invitation Suite
+25One set of wedding details in: invitation, RSVP, details, menu, place cards, sign and e-invites that match.


Questions
Do I need glasses to see depth?
Use red-left/cyan-right glasses for the intended binocular effect. Without them, the normal display shows the two color channels overlaid; perception also depends on the screen and viewer.
Where does the depth come from?
It comes from declared object coordinates and two camera positions. The package does not infer depth from a flat source image or claim the scene was photographed.
What costs depend on this workflow?
Scene construction and both camera renders are local, with no generation calls. More objects and larger canvases increase local drawing work; suitable viewing glasses are separate from the digital output.
What is already packaged in Stereo anaglyph shadowbox?
The domain algorithm and invariant checks. Runnable, editable example parameters. Control meanings, proof interpretation and limits.
Which parts of Stereo anaglyph shadowbox can add a charge?
Scene construction and both camera renders are local, with no generation calls. More objects and larger canvases increase local drawing work; suitable viewing glasses are separate from the digital output. Connections using a PopNow API key, including API-key MCP connections, spend from the separate API balance in USD. A ChatGPT or Claude connection authorized through OAuth spends website credits. These balances are separate; the quote shown by your connection is the approval basis.
How does Stereo anaglyph shadowbox differ from writing a prompt or my own skill?
The workflow supplies an explicit scene, camera pair and inspectable component exports. It avoids faking binocular depth with a single flat-image offset or an unexplained color filter.